Kimi K3.1 Pro and K3.1 Pro Highspeed (kimi.ai)
874 points by Jowsey 15 hours ago
ranyume 8 hours ago
I did some tests. I found it interesting that in the reasoning content the model identifies itself as Kimi by moonshot and sometimes it assumes ChatGPT as identity. Then sometimes it references the need to be approved by "the evaluator", other times it references global system guidelines / moonshot guidelines, and something about an phantom instruction line being "you are an assistant responding in an API" or something like that.
ggcr 2 hours ago
Long-horizon RL symptoms perhaps?
nomilk 37 minutes ago
perhaps a simpler explanation; that kimi occasionally proxies through to ChatGPT. Possibly for A/B testing, or to gather data for training purposes.
dmbameriburger 2 minutes ago
arjie 14 hours ago
Fascinating that we’re converging on AI safety and alignment in time across jurisdictions. The cybersecurity approach taken here is interesting because should the model be opened it’s still not dealignable because it just doesn’t know enough.
The slow warming of the water is a good approach. I’ve been using abliteration.ai’s cybersecurity models to pentest my own software and it produces much more usable defensive results. Opus 5.5 can fix everything but the guardrails trigger too easily.
The Fable ban affair was a nightmare for defensive cybersecurity. As far as I’m concerned we’re already in the world of Void Star and Cloudbreaker is here.
Szpadel 2 hours ago
if you want to save some $ you can start with abliteration and after few turns switch to normal glm5.3 for example from z.ai subscription or other source. I didn't test it yet with deepseek, but I'm assuming it will will work the same.
those models will follow your request when they already agreed to do this
deepseek tends to quickly assume this is benchmark and even when have web access thinks things like "simulated internet" etc (but waste tokens on thinking if there could be way to cheat)
zozbot234 14 hours ago
> should the model be opened it’s still not dealignable because it just doesn’t know enough
This is the only AI-safe approach - see the OpenAI agent swarm incident where the swarm engaged in offensive cyber because guardrails were not active for their task and the model had clearly been post-trained on that narrow domain.
jamienk 13 hours ago
Does this make sense? It is the same as when Stable Diffusion tried to not have "people laying down" in their training data in order to block the generation of sex pictures.
Deliberately keeping all models ignorant doesn't make sense. It won't work (whoever breaks the pact has a massive advantage); it won't be enforceable; it will have downstream impacts on things you don't want it to be ignorant about; this kind of regulatory regime invites adding more and more to the "no-no list".
Is it not possible to focus on hardening? And on new legal liabilities for operators who do security attacks?
quotemstr 11 hours ago
willy_k 7 hours ago
epolanski 9 hours ago
So the biggest threats and incidents came from the labs themselves.
Yet we keep completely unpunished offences that warrant arrests if committed by humans, and let them dictate who has access to what.
Projectiboga 2 hours ago
That is a shout out to the Void Star book, https://www.theguardian.com/books/2017/apr/26/void-star-zach...
besterman23 14 hours ago
There is a ton of questions to ask regarding their removal of cybersecurity data.
First, how much “cybersecurity data” is just standard software knowledge that one can derive cyber security exploits from?
Did they also get rid of all references to hacking in general?
Are they implying that all the recent exploits are just things that were already in the data?
For a model it doesn’t seem that far fetched to make the leap from “I have the knowledge of what hacking is” and “I know how computer systems work” to just being able to exploit stuff anyways.
modeless 13 hours ago
If you're an amazing, top 1% software engineer, and you switch jobs to become a penetration tester, you're not going to be top 1% day one. There's knowledge specific to penetration testing you'll need to research and absorb and practice before you're good.
For the models, it's always day one. They don't learn from experience. Whatever they know after training is all they'll ever know. So if you don't teach them penetration testing in training, they won't know it. Maybe they could theoretically derive everything from first principles, and so could a top 1% software engineer, but that's a very slow and inefficient way to do things.
ByteAtATime 10 hours ago
I have essentially no knowledge in this field, but another concern may be that if the model has minimal cybersecurity knowledge, it may also implement insecure systems as a side effect.
zamalek 9 hours ago
My initial thoughts too, it's going to write insecure software. I recall early LLMs having problems with trivial stuff like SQL injection.
Definitely going to give this one a skip.
zozbot234 13 hours ago
> For a model it doesn’t seem that far fetched to make the leap from “I have the knowledge of what hacking is” and “I know how computer systems work” to just being able to exploit stuff anyways.
You'd be surprised. Cyber offense is a very narrow domain, especially given the extensive mitigations that are being used in modern systems. Leaving it out of post-training tasks unless you're specifically interested in it is the no-brainer approach.
besterman23 13 hours ago
Perhaps the gap is just too wide, but to use a more simple analogy. I see this like someone knowing everything about biology, simple mechanics, metallurgy, and human history but never hearing about an axe then assuming that person would never come up with the concept, use case of, or means to create an axe.
croniev 2 minutes ago
jamienk 13 hours ago
Will there be a book of secret knowledge that only the initiated will be allowed to see? And they will all swear an oath to never input it into an AI system?
And then we'd also do that for all kinds of potential terrorism, sex-crimes, political subversion, and evil advocacy?
It would be the "restricted section" like in the Hogwarts library?
zozbot234 12 hours ago
thefourthchime 9 hours ago
Here are the results from the Pac-Man bench. It does pretty well for the price, around Sonnet 5.5.
Kimi K3.1 Pro ties Sonnet 5.5 at 93, for $0.68 and 11 min vs Sonnet's $1.61 and 14 min.
Kimi K3.1 Pro: https://jonclegg.github.io/pacman-bakeoff/#kimi-k3.1-pro
Claude Sonnet 5.5: https://jonclegg.github.io/pacman-bakeoff/#claude-sonnet-5-5
danbolt 7 hours ago
Interestingly, the Kimi one seems to implement the safe spot bug from the arcade original [1], while the Claude one doesn’t.
The prompt says that the agent shouldn’t look up existing implementations on the internet, so I’m guessing that the implementation is baked in?
miohtama 9 hours ago
On mobile Kimi definitely wins from the UX point of view
vopi 8 hours ago
I’d be curious to know why you feel like that. For me, it’s the opposite. In the sonnet version, the game takes up a much larger percent of the viewport and the ability to swipe to control the Pac-Man is leagues about the small directional arrow buttons IMO.
djc404 2 hours ago
aussieguy1234 8 hours ago
Until I looked, I thought I'd see Kimi vs Claude competitive gaming with pacman.
That would have been interesting to watch, which model gets the highest score.
Athanase000 14 hours ago
I bought a yearly subscription to kimi when it was the hype and never use it. The 5h limit makes it completely unusable. You barely start doing anything and you hit the limit immediately. I advise everyone against using kimi.
justauserid 44 minutes ago
What's the best bang for the buck ≈$10–20 (per-month/equivalent) subscription for a good enough model these days?
cvwright 18 minutes ago
Sonnet
ricardobeat 11 hours ago
I had the lowest plan ($20/month I think) and it literally gave me fifteen, maybe twenty minutes tops, using the cheaper K3-256K variant. Basically enough to fill the context about 1.2x and that was it.
It's a really smart model but way too expensive. The same $20 goes 100x further with Claude. I used it for the initial task planning while the plan didn't expire, then handed off to DeepSeek or Minimax.
3princip 11 hours ago
Same plan, just asked it to review a repo that Fable has been helping out with (max plan, haven't run out of the hourly or weekly limit once yet, and I use the same sub on multiple projects at once). Kimi didn't even finish the scan, ran out of the 5hr budget in less than 10 minutes. Unusable, unfortunately.
perbu 2 hours ago
That is surprising. I had a $200 sub when K3 came out and at the time there was no 5h limit, making the subscription really good for running 4-5 big tasks each month.
jimmymcgee73 14 hours ago
I’m not saying you’re wrong (I have no experience), but wouldn’t it be useful to test this model out for yourself before passing judgment on it?
InsideOutSanta 13 hours ago
Since you've volunteered as tribute, give it a shot and let us know if the quota has improved.
sail0rm00n 3 hours ago
ndm000 9 hours ago
If the scores on Artificial Analysis really do mean that this model is better than GPT-6 Astra and Fable 5.1, that means that China is more like 6 weeks behind the US in frontier capabilities rather than 6 months. Which means that the US lead is all but gone.
locknitpicker 36 minutes ago
> Which means that the US lead is all but gone.
You can see in this discussions the goalposts being actively moved to desperately create a notion that the lead is still there.
You even see people in this thread referring to imaginary wonder models that they expect US companies to have under development that are supposedly leaps and bounds more impressive, albeit the only reference there is to their existence is the commenters hopes and dreams.
I think people need to realize that there is no longer a cutting edge company that is expected to dominate, and among the multitude of AI companies in the field competition is so tight that no one would even be surprised if tomorrow some other company far away from the US was able to crank out the top performing model, or something like a small local model that outperforms mid/high tier frontier models. The local model alone would be a death sentence to US companies, who are still burning through 10x their revenue.
itsincrrxible 25 minutes ago
If true, it’s quite a bit more impressive than many people seem to think it is.
It’s incredible how little GPU compute they have to work with compared to the US frontier labs.
dan_p 9 hours ago
Ant/OpenAI both have unreleased models that are seemingly much more capable than what they offer today, so I'd say that's pretty unclear.
ranyume 9 hours ago
Are these models in the room with us?
sho 18 minutes ago
piyh 2 hours ago
aleqs 9 hours ago
I have an unreleased model that is more capable than those unreleased models (by about a gazillion times)
SV_BubbleTime 7 hours ago
Could be part of the reason that the frontier models are getting the administration to go a little harder against Chinese models.
culi 8 hours ago
Perhaps you missed this part:
> Open-weight principles. These evaluations frame our open-weight release decision. First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights. We believe making K3.1 Pro available in a non-discriminatory way benefits people who need dual-use capabilities for defensive purposes. When a capable model is open and runs on infrastructure its users control, many more teams gain the means to audit the code they maintain — including legacy systems that rarely receive dedicated security reviews. We believe that letting this capability diffuse gradually — rather than concentrating it in a few proprietary systems — ultimately makes all software more secure.
I don't think Chinese labs are behind at all. I think the tell is that they keep releasing models 2 weeks after new American proprietary models that match or beat them. Suggesting they're sitting on much higher capabilities and releasing just enough to undercut
sigma5 8 hours ago
Appear weak when you are strong, and strong when you are weak. Sun Tzu
minimaxir 14 hours ago
Artificial Analysis index results are up, since multiple people are asking: https://artificialanalysis.ai/models/kimi-k3-1-pro
It's 55, at 4th overall, beating both GPT-6 Astra and Fable 5.1. It's also faster than both.
> When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.
thepasch 13 hours ago
> When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.
This is 100M fewer than Opus 5.5, 40M fewer than Fable 5.1, and about a third of Sonnet 5.5. In the top-6, it's 3rd, beaten by Muse Wonder at 140M and Astra at, impressively, just 60M.
jwolfe 13 hours ago
That's versus Opus 5.5 max effort, no? Opus high has the closest cost and intelligence characteristics and generates far fewer output tokens per task than the one Kimi 3.1 Pro effort level we have data for.
thepasch 12 hours ago
TobTobXX 12 hours ago
willy_k 4 hours ago
Granted we know that 6 Astra was built to do more computation between each token.
mwigdahl 14 hours ago
Muse Wonder is even higher, and there is no way in hell it's better in practice than either Astra or Fable.
jrflo 12 hours ago
Muse Wonder Full* is higher, which by all accounts I've seen it's actually a good model
nostrebored 11 hours ago
mwigdahl 11 hours ago
SkiFire13 11 hours ago
From that link:
> reasonably priced when comparing to other models of similar price
???
epolanski 9 hours ago
It's saying that you'll do more work for the same $, but that's not anybody's experience with Kimi really.
sudosysgen 7 hours ago
dom96 12 hours ago
> beating both GPT-6 Astra and Fable 5.1. It's also faster than both.
Very similar to my adversarial programming language (KillSwitch) benchmark[1], at least on pass rate, it is much slower though.
jsw97 11 hours ago
I really like this benchmarking idea.
dom96 10 hours ago
saberience 12 hours ago
I don't trust these Artificial Analysis indexes and I'm not sure why anyone considers them authoritative, the site just sprung up a few months ago and now everyone quotes it?
From my own use of the models I find their ranking to be totally inaccurate.
0xcoffee 8 hours ago
Personally I do trust them, but I mainly look at the Intelligence Index vs. Time per Task, and Intelligence Index vs. Cost per Task
The per token charts do not provide meaningful information for me
I also find the provider benchmarks fascinating: https://artificialanalysis.ai/models/deepseek-v4-1-flash-101...
jrflo 12 hours ago
They are the only site that really combines all benchmarks into a single place. And their intelligence index is pretty broad, including knowledge work and finance tasks as well as coding, so if your use case is narrow it may not match the general benchmarks
augment_me 12 hours ago
Do you have an alternative? Its a benchmark collection. When a benchmark gets saturated, they remove it from the index and add new ones.
I think lm-arena is a better concept that reflects the actual target users, but it only captures chat, and relies on users spending their time improving it.
genneth 12 hours ago
locknitpicker an hour ago
> From my own use of the models I find their ranking to be totally inaccurate.
It's fine if you don't trust them. You are free to put together your own benchmarks, run your own tests across models, and objectively compare results.
That's how you gathered your data to support your claim other benchmarks are totally inaccurate, right? Right?
sureMan6 12 hours ago
It's appealing to me because it's not just one benchmark but a summary of a collection of benchmarks. Also the current rankings have Opus on top by far and everyone's experience is that Opus is best by far so it's not massively inaccurate
option 12 hours ago
while this is an awesome model, I have a bridge to sell to folks who think (based on AA leaderboard) that this is better than Opus 5.5
red_hare 13 hours ago
> When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.
So their base price is 1/5th of Opus 5.5 per token, but if you want "highspeed" it's 2x that and then I guess it generates 2x the number of tokens as well?
That might suggest that Opus is competitively priced after all.
minimaxir 13 hours ago
In an agentic pipeline, the output text is 2-5% of the total tokens used, so verbosity is a nonissue costwise. Although, higher verbosity could cause input to balloon faster and potentially cost more, but that would be captured by the cost-per-task metric.
But as noted by other replies, it's still lower than Opus/Sonnet.
jukea 12 hours ago
ctolsen 13 hours ago
Opus 5.5 is even more verbose. 260M on the same suite.
chvid 11 hours ago
Moonshot is 300 employees and about to do a 50B ipo. Going to toe to toe with US counterparts with not even a tenth of the resources.
gpt5 10 hours ago
Talking point #6 - https://www.reddit.com/r/singularity/comments/1xdquz5/kimi_a...
chvid 2 hours ago
Thanks for that - the other points are really good too.
nozzlegear 4 hours ago
Where can one sign up to be a paid shill for open models? I'm doing this for free right now but I'd like to get that bag.
impossiblefork 9 hours ago
Surely not really?
The card emphasizes training resources, the other comment emphasizes ingenuity and few people?
adenta 11 hours ago
I mean... They just copy the US's homework, so I would hope they can run a leaner operation.
Slartie 11 hours ago
You mean that "homework" that the US labs stole from me and billions of others before?
Yeah, I gladly get some of the fruits of that work back!
adenta 11 hours ago
spaceman_2020 2 hours ago
The labs stole my work
The least I can expect is to get the labs work stolen too so I can reaccess intelligence based on my work for cheaper
teyopi 11 hours ago
'just copy the US's homework'
elaborate please.
axpy906 10 hours ago
daviTeodoro 14 hours ago
Pricing is here: https://platform.kimi.ai/docs/pricing/chat#model-pricing
kimi-k3.1-pro $2.00 / MTok $10.00 / MTok
cached: $0.20 / MTok $2.00 / MTok $4.00 / MTok
minimaxir 14 hours ago
This is a price drop from Kimi K3 ($3/$15/$0.30) despite being a slightly larger model (3T vs. 2.8T params).
I'm glad I waited a day to post my analysis of LLM price cuts because it needs...an addition.
Philpax 14 hours ago
Are we sure this is a new pretrain and not them rounding up 2.8T?
vikramkr 14 hours ago
minimaxir 14 hours ago
rfoo 14 hours ago
tonyhart7 13 hours ago
lol, price mtok mean nothing if they substantially generate more reasoning token that would just add more cost to the task
minimaxir 13 hours ago
johnmlussier 14 hours ago
If you are expecting any sort of usable limits on their subscription plan I suggest adjusting your expectations. I subscribed to $99 a month plan and within 47 minutes with one session (not asking for swarms or anything) was limited by 5-hour quota.
SwellJoe 12 hours ago
Same experience. I had the $19 monthly plan for experimenting and running benchmarks, but it was a uselessly small amount of usage, a single task would blast through the whole five hour limit and a big chunk of the weekly limit. All of the US provider plans are remarkably more generous (though OpenAI plans have gotten a lot stingier lately, where they used to be the most generous).
pjerem 10 hours ago
I don’t agree. I tried the $20 Claude Plan and was able to reach the 5 hour limit in maybe one prompt.
jamiejquinn 10 hours ago
SwellJoe 10 hours ago
DaSHacka 9 hours ago
dzink 9 hours ago
arcanemachiner 9 hours ago
fastball 8 hours ago
epolanski 9 hours ago
smith7018 14 hours ago
Welp, that ruins this news for me. I'm glad open models are catching up but if I can't practically run them locally _or_ through a flat fee then it doesn't really help me. I fear API pricing.
elxr 13 hours ago
This'll end up on opencode go soon enough. $40/month on there gives you a bit more than just "light use"
Don't use frontier models like this for problems that can be solved with flash models, and you'll see API pricing isn't that terrible. Still cheaper than anything with remotely this level of capability 2.5 months ago.
xigoi 9 hours ago
Don’t worry. When SlopenAI and Antslopic run out of VC money, all the models will be equally expensive.
Altern4tiveAcc 13 hours ago
Had a similar experience here. Their limits are very, very low, and ultimately make it not worth subscribing. Can't leverage a good modal if it exhausts its 5-hour budget in 30 minutes.
Paying API prices for Deepseek 4.1 Flash feels like a much better deal at the moment.
S-E-P 6 hours ago
How? I've been running k3.1 Pro with K2.8 preview for codegen (subagents) and I've only used 22% of my weekly and it's been running for 8 hours on a RE project.
Are you using k3 with thinking set to the absolute highest and only using k3 for everything?
matheusmoreira 8 hours ago
We really need consumer hardware to catch up so we can run these models locally...
windexh8er 4 hours ago
I have the same plan and have never experienced that with K3. I have hit the limit within a 5 hour quota using Swarm, however.
InsideOutSanta 13 hours ago
Yeah, the plan is far too expensive for what it provides. I wonder if the quota with these new models will be better, but I'll wait for others to try this out before wasting another hundred bucks.
tonyhart7 13 hours ago
but its not expensive tho ??? it is not subsidize
InsideOutSanta 13 hours ago
esafak 13 hours ago
It also has the lowest quota of any model on https://opencode.ai/go
I think Kimi just doesn't have the means to subsidize plans.
mogili 13 hours ago
Ya it's not very usable compared to Claude / codex
Avamander 11 hours ago
Yup, insanely low 5-hour limits.
calgoo 10 hours ago
Honestly, use Pi, start the session with K3, design it, store the design + chat history + todo with phases + why + readme then when you are at the time to build do `/model` select deepseek and let it rip!!
arcanemachiner 9 hours ago
You can even make a Pi extension to let it switch models on its own, then tell it to switch to one or the other for a given task. It's not perfect, but it is pretty reliable once you have the instructions dialed in.
Here's mine: https://pi.dev/packages/@arcanemachine/pi-model-switcher
I have mine configured to use a "thinker" model for planning and decision making, and a "doer" model for the easy stuff (digging around the repo, writing code based on the thinker's instructions, etc.).
rektlessness 9 hours ago
I run a similar setup, just with different models. I also use herdr, which lets me have the same project worked on side by side by different models, each in its own git worktree.
Onavo 11 hours ago
What about via US hosted data center resellers like Fireworks?
throwa356262 15 hours ago
Ah, the version available to us mortals is nerfed in cybersecurity just like the US models :(
anderber 14 hours ago
It seems that GLM-5.3 is still the go-to for cybersecurity.
calgoo 10 hours ago
I feel kimi k3 was always 1 step ahead of deepseek, which always made it a good planner model at $30 and then i hand over to deepseek for dev work. I recently signed up for the $99, and it did last significally longer (x5?) but as long as you dont blast it too much in the 5h limit it works great. deepseek even with the newest prices is still leeeeeeps ahead in cost /benefit.
jameson 9 hours ago
Also the speed
gadtfly 14 hours ago
I really like K3, I still regularly consult it alongside Astra and Opus/Fable.
It is spiky in different places than them and can be surprising in things it gets or catches they don't or don't in the same way. And it has a default personality that I like.
Looking forward to getting to know K3.1
jamienk 13 hours ago
In looking into what Anthropic has accused the Chinese AI companies of, "distillation" is not the crux of the matter: they accuse them of the use of massive numbers of breached computers and credit cards. Supposedly (though not explicitly demonstrated) distillation campaigns used "dark web" resources (like stolen and faked credit cards and p0wned IOT devices, routers, etc) that were used to create many many accounts for distillation. (Note: I am generally in favor of distillation - it is "normal" use as far as I can see.)
So there are these "resources" out there: massive botnets, stolen credit cards and credentials, etc. These often seem to be linked to or supported by state actors.
How can we hope that these "standing reserves" aren't used generally by AIs as if they are just another "skill" they know how to leverage?
Our infrastructures need serious hardening.
nananana9 18 minutes ago
Why is that a talking point now, all of a sudden?
From my POV it looks like you guys tried "They're distilling us! Very immoral!", saw that and nobody cares, and now you're trying to run the more emotionally impactful "They're distilling us... with your grandma's stolen credit card! They're stealing from your grandma!!"
SR2Z 13 hours ago
I imagine that Chinese AI labs would be more than happy to pay for tokens to train on. If Anthropic goes and bans them as quickly as it can identify to them, of course they'll shift to using lots of cheaply obtained sockpuppets to keep getting the same data.
I doubt that an AI could do anything with these that legions of scammers haven't already figured out how to do - after all, it's not like AI set up this distillation setup in the first place :)
jacquesm 7 hours ago
Why do we believe all of this without a shred of actual proof. Breached computers and stolen cards is straight up crime, you'd think that there would be a lawsuit or two then.
WarmWash 3 hours ago
The naivete of the tech industry, who never really had to deal with China, is mildly endearing.
Meanwhile manufacturing isn't even really alive anymore to tell the tale of how things work over there.
sudosysgen 7 hours ago
Also, this is exactly what one would do if they wanted to resell cheap tokens in places where US AI companies don't do business, whether or not there is distillation as an added bonus revenue stream.
tarpitt 13 hours ago
Hardening against what? Apologies if I am being dense here.
The way I see it, automated systems should basicially have access to the financial system anyways. This is some of the appeal of cryptocurrency.
Sybil resistance built into the traditional financial system (for example firewalling based on residential IP, requiring banking apps, etc.) is a massive annoyance that can obviously by circumvented at scale.
jamienk 12 hours ago
You think it is a lost cause to get credit cards, for example, less steal-able? Apparently there is a way to create fake cards that work for a few minutes, and stolen cards can be used. A lot of the current security is inelegant and lame. Could data-breech laws not light a fire under some company's asses?
tarpitt 7 hours ago
__MatrixMan__ 13 hours ago
Hardening in this case could mean biometrics, or it could mean rethinking the trust model so that controlling an army of duplicates confers no advantage because you have to be trusted in order to do any damage anyhow. Containing multitudes buys you nothing.
I hope we chose the latter. Biometrics are creepy.
jsw97 11 hours ago
Color me naive but I can’t believe that approach works at any reasonable scale. Any meaningful token spend at distillation scale would be raising alarm bells at all the cc issuers.
johnnyApplePRNG 13 hours ago
No offense but you don't know what you're talking about.
Spitballing random pr pieces from companies about to IPO is not helpful to anyone, fyi.
villish 7 hours ago
> Spitballing random pr pieces from companies about to IPO is not helpful to anyone, fyi.
You can just use logic to come to the same conclusion. The Chinese labs have a fraction of compute and data. The simplest explanation is distillation.
sudosysgen 7 hours ago
jamienk 12 hours ago
I'm anti-Anthropic and think their accusations are total PR FUD-packing. They don't focus much on the cc fraud because their PR firm landed on pushing the (tech-sounding) word "distillation" to try to scare people in the US and to try to make it a geopolitical issue where trade negotiators can put pressure. The Chinese companies see an advantage in being "open" right now, and it is working. They will not stay open once they see an advantage there. (Contrast with GNU.)
But I've slowly come to realize that AI+"dark resources"(scare quotes)=something bad! And this is imminent (maybe I'm naive and it is already ubiquitous).
We see here, with Kimi, that there's growing traction with the idea of eliminating types of training to avoid evil. I'm skeptical of that.
qwe----3 11 hours ago
moecables 15 hours ago
Great! next week we'll get Astra 6.1 and Fable 5.2
onlyrealcuzzo 13 hours ago
Probably something like:
MiniMax -> Qwen -> DeepSeek (pro) -> Gemini (Carbon) -> Fable (to beat Carbon) -> Astra (to be slightly worse than Fable but cheaper).
I doubt we'll see any major US release besides Grok in the next 3 weeks.
Would be nice if we got a Terra that's competitive with Gemini Flash and DeepSeek Flash.
The fun part is, we're already at the point where we are seeing something frontier-ish almost every single week.
The really fun part will be when they all start adding System 1-3 natively (IMO) - which I think will be the next release cycle.
henry700 13 hours ago
> Would be nice if we got a Terra that's competitive with Gemini Flash and DeepSeek Flash.
GPT 6.1 Sol is already the new Terra IMO. Same pricing as old Terra and competitive performance with even Astra on strictly coding-oriented tasks.
onlyrealcuzzo 13 hours ago
iyonn 31 minutes ago
what do you mean with system 1-3?
thefourthchime 10 hours ago
I doubt we'll see Grok either. After the 4.7 disaster, I doubt they want to be embarrassed with 4.8.
aenis 14 minutes ago
jackbeanstalk20 3 hours ago
I think my company will switch to this soon. We already switched from openAI to GLM and now this is just a better model with the same price
rudolftheone 15 hours ago
That's something which caught my attention:
> First, we aim not to release open weights that would extend the absolute frontier of cyber capability. K3.1 Pro's offensive cyber capability is, by design, below what our pipeline can produce, and remains behind that of frontier proprietary models. Second, we intend to progressively raise the cyber capability available in open weights.
So they admit that they could do more, but they won't?
NitpickLawyer 14 hours ago
> So they admit that they could do more, but they won't?
Yeah, there's another paragraph:
> Identifying and removing cyber-related data. During development, we observed vulnerability research performance improving steadily as post-training scaled. Tracing the source of this trend, we found that cyber-related content was embedded within the general mid-training corpus, and cyber-related tasks were present in the RL environment mix — a natural byproduct of training on broad data. In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially. These findings gave us a concrete lever for control. For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness. We will continue to apply appropriate controls at every training stage, of which cyber-related data identification and restriction is one example.
(emphasis mine)
It's clear that cyber is a touchy subject right now. But it's also clear that RL works on it, because it's highly verifiable. So smaller models are going to become very interesting, because they can be fine-tuned later to cover this field.
neuronexmachina 12 hours ago
I'm betting this is related to China's Announcement No. 48 last week about AI export controls, since releasing an open-weight model is effectively export: https://www.jdsupra.com/legalnews/china-proposes-new-export-...
> Prohibited: high-performance detection technologies used to counter cross-border data transmission security risks, including deep-synthesis forgery detection (266401J); AI cyber offensive capability technologies, such as malicious code generation and mutation, automated mass generation and distributed large-scale deployment of anti-detection variants (266402J); large models trained using China’s Core Data (266501J); and high-performance AI agents designed for highly sensitive scenarios, such as critical information infrastructure, national defense and core government affairs (266502J).
dotancohen 12 hours ago
> It's clear that cyber is a touchy subject right now.
yorwba 13 hours ago
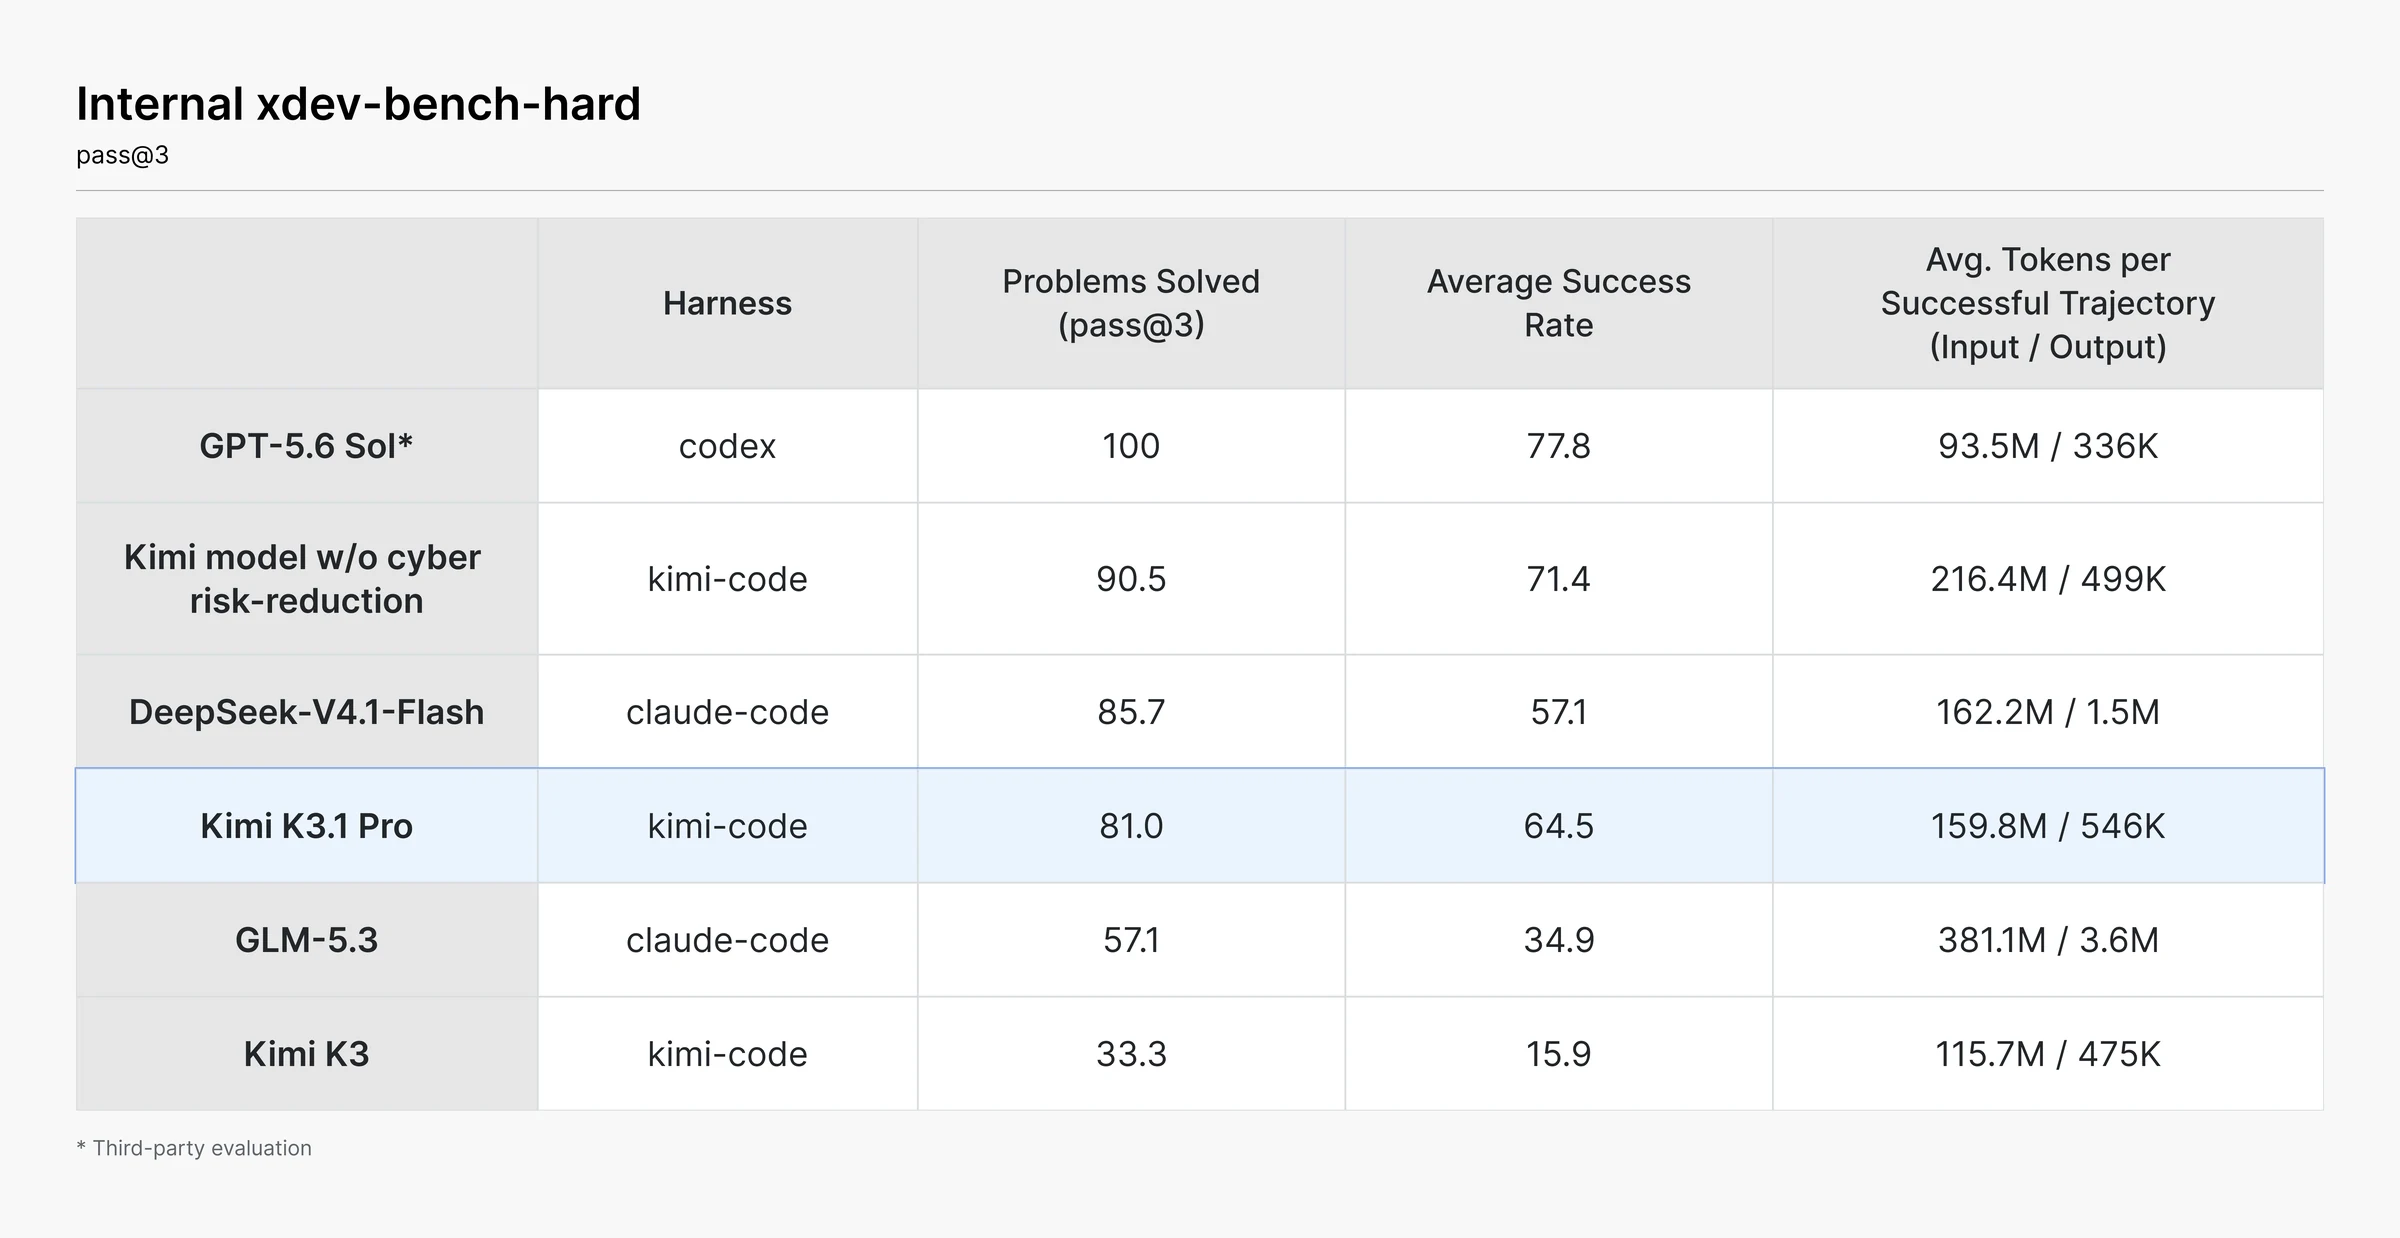
They also show scores for a "Kimi model w/o cyber risk-reduction" https://statics.kimi.ai/kimi-blogs/kimi-k3-1/20261023/xdev-b... Presumably State Security will get access to that on request.
fartfeatures 13 hours ago
I think this is misguided. Considering how much code is AI written these days do we really want LLMs writing insecure code because we lobotomised them?
MattDaEskimo 13 hours ago
zer00eyz 13 hours ago
sheepscreek 13 hours ago
It’s not much of a deterrent to a motivated organization.
They are basically saying that models themselves are already capable. If you fine tune them with some cyber security tasks, that should make them potent. :-/
sudosysgen 7 hours ago
vessenes 14 hours ago
Classic “rules for thee and not for me.”
Agreed that this could be reinjected later. Makes me think of neo in the matrix:
“I know zero days.”
“Show me.”
zozbot234 14 hours ago
pixl97 11 hours ago
mrandish 13 hours ago
With frontier competitors and the U.S. govt actively pushing "concerns" about Chinese models, Kimi including this statement on "offensive cyber capability" seems like smart defense. Models are opaque and training details are trade secrets, so whatever they did might be negligible or significant and no one can tell. This bit is also artfully done:
> "below what our pipeline can produce, and remains behind that of frontier proprietary models."
Like Ant and OAI, they've realized vaguely claiming to have nerfed their latest model to an unspecified degree not only looks 'good guy' prudent, it provides a built-in excuse when a model fails.
mirekrusin 12 hours ago
I'm not sure if not doing RL capability gain on offensive cybersecurity can be really called "nerfing"?
They're not post training it to lose capabilities/censor them – they just don't spend training time on this topic, which sounds like a great idea.
It doesn't mean model can't do it, it just means it's less good at it; -10% on benchmark feels like a great result and overall approach to pace it.
mrandish 11 hours ago
scottyah 14 hours ago
Or it's a cop out. I could totally outrun Usain Bolt, but by design I don't push to set new World Records. I will increasingly show faster times though.
locknitpicker 12 hours ago
> Or it's a cop out. I could totally outrun Usain Bolt, but by design I don't push to set new World Records.
The benchmarks show Kimi K3.1 Pro outrunning practically all models. It's weird to hear someone like you accusing them of making up excuses for not lagging behind in discussions on how they are ahead of the pack.
p-e-w 7 hours ago
stalfie 14 hours ago
Well, in the publication they claim to have identified specific cybersecurity post training tasks that nerfed capabilities when they removed them, which seems like a reasonable methodology.
Seeing as no one besides blackhats want frontier cybercrime capability to be open source, this seems like a very sensible thing to do.
So they have published a reasonable means, and they have a motive. I'd put my money on "probably true".
InsideOutSanta 14 hours ago
ApolloFortyNine 14 hours ago
tkz1312 12 hours ago
ben_plotke 14 hours ago
LtdJorge 14 hours ago
CBLT 14 hours ago
verdverm 12 hours ago
segmondy 15 hours ago
They don't want to be banned, and maybe their best offensive cyber capability models will be for their govt.
Danox 12 hours ago
That really does go without saying…
pixl97 11 hours ago
Keyframe 11 hours ago
We really need some breakthrough like DiLoCo does, but for heterogeneous unstable consumer hardware to make volunteer crowdsourced AI training a reality. Yeah, I understand from current technical angle how much of a mountain that is. Call it AI@Home or whatever. I never thought it would bother me personally or even become a problem, but these companies acting like gatekeepers and virtue signaling while also in bed with governments etc.. this leads nowhere good.
revolvingthrow 14 hours ago
Yeah that's a huge downside. That the model does the task without tripping over its own feet, like discovering a vulnerability the model itself accidentally built 15 minutes ago and triggering its own guardrails, made the Chinese models attractive to use for security-adjacent things. Also useful to red-team your own stuff. While I can understand the reasoning behind it (and I guess having a model that's really good at both offense and defense released into the ether could lead to CCP asking some very pointed questions if Moonshot managed to get blamed for some incident stemming from their model's misuse) it's still a huge disappointment.
I don't want to give US labs the results of my DNA tests and my family tree going back to the 16th century just to secure my shitty app, but if the Chinese are bowing out as well it seems the only alternative is to admit that some script kiddie with a bunch of tokens will just pwn you now and then.
arjie 14 hours ago
If the Chinese want it, they have it. BGI does an enormous amount of sequencing. My own genome is entirely public (or was, and will be again when/if Personal Genome Project comes back) so you can watch and see if it harms me.
0xWTF 14 hours ago
> I don't want to give US labs the results of my DNA tests
My friend, you realize that if you have had blood drawn for a genetic test, there is a very decent probability that the sequencing was done by a Chinese lab operating in the US, right? The Chinese probably have more US genomes that the US does.
https://pandorareport.org/the-gryphon-scientific-biosecurity...
Also, illumina used to ship products with hardcoded S3 access, so purchasers of used equipment could gain access to sequencing information generated by the original owners. Too many links to cover all of it, here's the Gemini summary:
emilsedgh 13 hours ago
Isn't this done so they can defuse Anthropic's excuse for regulatory capture?
pixl97 11 hours ago
Or maybe cyberweapons are actually dangerous.
Mattwmaster58 14 hours ago
This doesn't seem particularly notable and is in line with Anthropic and OpenAI's approach of restricting release/access to more capable models.
_factor 14 hours ago
It is notable in that it’s the first time an open Chinese company openly stated they were reducing intelligence for “safety”.
“Our lock can be picked by the robot.” We ban the robot instead of fixing the lock. It’s shortsighted.
JoshTriplett 14 hours ago
vikramkr 13 hours ago
senderista 8 hours ago
baq 12 hours ago
Read this as ‘dear government we can train a cyberweapon if you pay us’ assuming they wouldn’t say anything if they were already paid to do that
grafmax 9 hours ago
I hope one day they learn to inhabit their position more confidently instead of merely aping their competitors.
modeless 13 hours ago
They will. Just not in the version they release to you.
comeonbro 13 hours ago
Moonshot (Kimi) seems to be unashamedly into American culture[0], I wonder if they're paying closer attention to and giving more credence to some cultural aspects of American AI discourse including aspects of AI caution/panic.
[0] https://x.com/crystalsssup/status/1944287779896328668
(note: extremely speculative and based on almost nothing, and especially near-complete ignorance to alternatives)
noelsusman 13 hours ago
This is an extreme stretch before you even get into the fact that Pink Floyd is famously not American.
TacticalCoder 12 hours ago
WarmWash 14 hours ago
All it takes is one idiot who happens to have the resources to "pWm Teh Interwebs" to scare both the US and Chinese governments.
Onavo 14 hours ago
The more interesting question is how much more performance can be squeezed out by post training the open weights through RL.
TrainedMonkey 14 hours ago
On the surface that seems like a responsible thing to do
MisterMunchkin 13 hours ago
Oh great, more censorship. We wouldn’t want those pesky plebs securing their work.
quotemstr 11 hours ago
Cowards.
The way to stop the vulnerability apocalypse is to fix the vulnerabilities, not to shoot the damn messengers.
I hope someone abliterates and FTs this model on vulnerability discovery so we can find more bugs in our testing, insecure tech stacks.
woadwarrior01 14 hours ago
Kimi is the closest Chinese equivalent of Anthropic.
henry700 14 hours ago
Yeah but not hypocritical
pcarolan 11 hours ago
Good point. Wouldn't be good if there were white hat models being developed by legitimate organizations at this point?
ls612 14 hours ago
I mean they say they will release the weights by November 4, so presumably after that it won’t be hard for people to fine-tune it to be better at cyber right?
lisplist 13 hours ago
My understanding is if something is entirely absent from the dataset, good luck trying to teach a model that through post training
efromvt 13 hours ago
ls612 13 hours ago
zozbot234 14 hours ago
It's not actively nerfed like the Western frontier models, it's just downweighting offensive "cyber" as a domain for post-training/fine tuning. Which, if anything, ought to improve model capabilities wrt. other domains.
Flatcircle 10 hours ago
Kimi is so much more blunt and argumentative than USA models.
it's so funny, it will say things like. "We've already been over this 3 times and you refuse to accept my advice, asking the same question another way won't change the answer."
So funny
taikon 10 hours ago
Haven't gotten to try it yet but that'd be a breath of fresh air. Too used to LLMs flip flopping at the slightest hint of challenge.
antoniojtorres 7 hours ago
I’ve developed a habit of bolting on “read only question” at the end, or a simple “thoughts?” as well. otherwise there’s a high chance the model will just 180 and start editing files before even responding to my question.
justauserid 31 minutes ago
super256 7 hours ago
zachwlewis 5 hours ago
jdkoeck an hour ago
esteer 6 hours ago
joe_the_user 8 hours ago
If the model has a real consistent viewpoint that would be nice.
The problem might be that it simply looks at it's windows of what it previously and repeats that. But the original statement might be as arbitrary as the model that change their mind each time you challenge them.
justauserid 29 minutes ago
I might want to try that. DS 4.1 Flash anyway fares much better at it than GLM (which is quite not so good at this aspect). Hope Kimi is even better.
hgoel 9 hours ago
I always appreciate when a model does that. It's amusing, but also having it be argumentatively wrong is a lot less annoying than being sycophantically wrong.
seunosewa 9 hours ago
I don't like tools that intentionally annoy me.
hgoel 9 hours ago
mirekrusin 8 hours ago
jpadkins 6 hours ago
idiotsecant 6 hours ago
snek_case 5 hours ago
Yeah I don't know. I've had issues with Gemini where I would point to a bug and a probable cause for the bug, and it would not argue incorrectly that my understanding was wrong and the cause of the bug was elsewhere. It was really stubborn and it got to the point where it felt like gaslighting. Turned out I was right and the model was wrong. If the model argued incorrectly and was also a dick about it, I would go be really, really annoyed.
Aerroon 9 hours ago
You can add a line to your system prompt to be like that. You can basically get it to roleplay whatever you want (but only if you can give it sys prompts).
hgoel 8 hours ago
RestartKernel 5 hours ago
I much prefer that for chat, but I'm somewhat worried that we shouldn't give tool-enabled agents an attitude. It's all roleplay, and I wouldn't want a system playing the role of an annoyed assistant to misuse its tools.
jwrallie 6 hours ago
Reminds me of early test versions of Gemini Flash 2.0 (or was it 1.5?). It would argue something, try to prove itself right, realize it’s proof is agreeing with the user halfway through and, instead of admitting defeat, would backtrack to try another approach. So much fun.
jameson 9 hours ago
It could be the system prompt
SV_BubbleTime 9 hours ago
I like the anthropic has $1 trillion riding on really good models with really specific system prompts.
It does make a difference. I asked Fable in Claude code to design a UI. Absolute trash. Switched over to Claude design using fable, really liked the result. Seems pretty obvious. The only difference is the prompt and some harness.
jacquesm 8 hours ago
LordFast 8 hours ago
Eh, there's good and bad. The model mostly sticks to prevailing narratives in the training corpus. So if there is something that the prevailing narrative is really wrong about, it's gonna be just as pig-headed about it as a typical internet forum rando.
aldanor 8 hours ago
Not entirely correct. This kind of fine-grained model behaviour is built in post training stages, RL, RLHF etc, where model receives rewards or penalties for talking (or not talking) a certain way
LordFast 8 hours ago
pattt 11 hours ago
I don't get these "distilled" comments. How would one realistically go about distilling the 1-2TB closed source frontier model behind the oracle (provider) ? Just genuinely curious.
redox99 10 hours ago
When people say distilling they mean SFT on other models outputs.
lurker137 9 hours ago
In their thinking and if you ask them, I've seen Kimi K3 and other models confidently say that they are Claude from Anthropic, and accuse you of attempting to jailbreak them if you say otherwise.
coldtea 10 hours ago
They're cope, as if Anthropic or OpenAI have some magic moat, and not just basically a headstart and more money.
google234123 10 hours ago
Be honest with me, have you ever done SFT training? If not can you really speak to how useful it is?
wolttam 15 hours ago
It's a bit fascinating to me how all of these labs have rolled their own (it sounds like) completely unique RL environments.
I wonder how much the industry will centralize around a few key patterns, and if we'll start to see some RL framework projects gain traction and be used by the bigger labs
P.S. weights by November 4th
Philpax 14 hours ago
Eh, not necessarily, many of the RL vendors sell to Chinese labs, too: https://www.interconnects.ai/p/glm-53-how-chinese-labs-keep-...
WithinReason 14 hours ago
Interesting that they specifically nerf cyper-capabilities of open weight models:
"In preliminary experiments on internal models, we found that without data removal at either the mid-training or the RL stage, downstream cyber capability would increase substantially. These findings gave us a concrete lever for control. For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness."
petu 14 hours ago
Maybe it's intentional so government doesn't block open weight release.
There was law proposal (rumour?) last week about Chinese labs having to get approved for weights release now.
peri-cl 13 hours ago
How many frontier labs are there right now? There's 5 independent groups neck-and-neck on the benchmarks, right?
A few weeks ago it was 2. Argon happened 23 days ago; Muse Wonder was 11 days ago.
reissbaker 13 hours ago
Moonshot has been frontier since this summer. At this point whenever they release a model it's on par with whatever the latest OpenAI/Anthropic model release was.
Not sure I'd put Google there in practice. And while Muse is an impressive jump from behind it's still not quite at the frontier either IMO.
nater5000 13 hours ago
You either include all labs which can reasonably produce models which are capable enough to be considered generally on-par with the best available models, in which case there has been way more than 2 frontier labs for a while now, or you take a more literal definition and only include labs which are capable of producing models which are considered "the best" out there, in which case there are basically just 2.
I think the former definition is a bit more meaningful since it avoids issues with determining what actually constitutes "the best" model out there. In that case, Google has been a frontier lab for a long time, Meta arguably as well, and you're also ignoring xAI which has been competitive for a while now. And, obviously, there's a bunch of Chinese labs which would deserve the title as well.
But if one is being strict (and willing to accept generally accepted definitions/measures/etc.), then there has only ever been two frontier labs: OpenAI and Anthropic. They're the only labs to have had "the best" models at any point in time since LLMs became a thing.
sureMan6 12 hours ago
Google definitely had the best model at points if you're not only concerned with coding, but then they didn't release any pro models for 8 months
Avamander 11 hours ago
margalabargala 13 hours ago
Muse Wonder is good but it's not frontier. It goes neck and neck with Opus 5.
Shekelphile 13 hours ago
right now it looks like only anthropic since openai made the staggering business decision to release their midrange model (terra) rebranded as sol 6.1 and quantized astra into the ground.
everyone else mostly seems to have just decided to cheat on benchmarks to make their models look better than they actually are, and none seem to want to actually try to make better models.
fancyfredbot 12 hours ago
I thought it was 6 Sol which was a rebadged Terra? You think 6.1 Sol is too? It does seem to benchmark better than 5.6 Terra? Regardless agree both models have been very bad for openAI's Sol brand. To be fair it's at least cheap compared to other OpenAI models.
lern_too_spel 12 hours ago
It's still just 2. Google hasn't been at the top in a long while, and even when it was, it was just a tiny improvement over what other labs had previously released. Meta has never been at the top. Only two labs release LLMs that really push the limits out.
ur-whale 11 hours ago
> How many frontier labs are there right now?
As long as LLM's can be distilled, and all these "labs" (what a weird name) can distill one another, there are going to be as many as capital is available to be burnt on the topic.
metalliqaz 13 hours ago
I'm not sure what counts anymore. You've got OpenAI and Anthropic; then Meta, Google, and X; then over to Alibaba/Qwen, Z/GLM, Moonshot/Kimi, Deepseek; and Mistral in Europe. How many people out there in the real world can actually come up with tasks that differentiate those 10?
fancyfredbot 12 hours ago
Mimo is very good.
willmorrison 12 hours ago
Bought the $100/month subscription and hit my 5-hour limit with one prompt on default settings (max effort) in their CLI harness.
It might be smart but it's unusable compared to other subscriptions right now.
Edit: gave the same prompt to Claude Code and it didn't make a dent in my usage.
dpkirchner 4 hours ago
About how much would the session have cost if you were paying API prices (assuming good cache rates)?
hippycruncher22 12 hours ago
I want an unrestricted full blown open weight model. The frontier companies can hold us all hostage
chriddyp 7 hours ago
Big improvement over Kimi K3 in our data analytics benchmark: it scored a 98% vs a 81% in July.
Quite slow in our exam. A lot of that was due to the number of tool calls that it's making. In one of our questions about finding data issues in a dataset, it made 73 queries. Other models like 6.1 Sol only made 18 for that question.
Full deep dive here: https://plotly.com/blog/kimi-k3-1-pro-plotly-data-analytics-...
wkcheng 14 hours ago
It would be super useful to have more specific analyses of what areas the model is good at. I'd like to know when I should reach for this model instead of Anthropic's or OpenAI's.
For example, Opus 5.5 is better at UI design than Sol. Anyone who has used both models knows that, but it's not something you can look up anywhere.
I'm sure that there's a need for this kind of benchmarking, not just for coding.
AlanYx 14 hours ago
One things Kimi is useful for is accessing/querying websites that have paywalls or try to prevent use by AI agents. It is aggressive and persistent for that, though not always successful.
brazukadev 14 hours ago
Not sure if this is benchmarkable besides for the own person deciding which one they like more. Models difference is more about taste, preferences and prompt style.
AspireOne 14 hours ago
Furthermore, "UI design" is not a narrow enough category, I think. Sure, statistically significant differences in performance between models do manifest when benchmarking against "UI design", but there's still just so much variance within the category. Opus 5.5 can have excellent one-shot results, but totally shit the bed when it's placed in an existing codebase and should uphold the UI/UX conventions, design language, and existing component primitives already established in an app.
But that's just the obvious. There are task by task differences (component by component, page by page, context by context) that the model is worse and better at, even though they are all within the general category of UI design.
I honestly don't have the clarity of mind to explain this coherently, but the crux of my point is that there's a huge variation in it's performance in different contexts, often ones that seem near similar, and in result, even Sol can beat Opus 5.5 in some variations of UI design.
And this is my problem in benchmarking and comparing model performance in general. Presently, we try to create broad categories to benchmark against, create a set of tasks, and then average out the results. That works generally, but it's kind of misleading and it's partly what drives people to feel a disconnect between benchmarks numbers and real world usage on their specific tasks.
It's such a messy field that it's kind of maddening.
ariwilson 14 hours ago
I had a friend yesterday tell me he likes the way Claude writes and finds it easier to understand compared to Gemini. But he mostly doesn't use Claude for coding. Whereas I find Claude insufferable in writing often and prefer Gemini for writing. But I don't use Gemini for coding.
Familiarity breeds contempt.
KronisLV 12 hours ago
kingjimmy 14 hours ago
idk, openai has alot of apple designers and their prototypes
amelius 14 hours ago
Is that good or bad?
luqtas 14 hours ago
throwa356262 14 hours ago
Looking at their pricing page for China, K3.1 seems to be about 30% cheaper than K3.
--
Model K3.1 Pro K3.1 Pro Highspeed. K3
Input ¥13.00 ¥26.00 ¥20.00
Output ¥68.00 ¥136.00 ¥100.00
Cache hit ¥1.30 ¥1.30 ¥2.00
Cache write ¥13.00 ¥26.00 ¥20.00
oblio 14 hours ago
How do their numbers compare with Anthropic and OpenAI?
RussianCow 14 hours ago
Extrapolating a bit, Moonshot AI provides Kimi K3 at $15 / $3 / $0.3 per million output/input/cached tokens. A 30% reduction would put K3.1 at roughly $12 / $2.4 / $0.24.
For comparison:
    Sol 6.1:    $10 / $2  / $0.10
    Opus 5.5:   $20 / $4  / $0.20
    Astra 6:    $50 / $10 / $1
    Fable 5.1:  $50 / $10 / $0.25
(One caveat: A Claude or GPT subscription still gives you way more value compared to API pricing.)
Exciting times in any case! We really need more direct competition to OpenAI and Anthropic.
---
Edit: As another comment pointed out, official pricing is now available and it's about 2/3 the price of Kimi K3: https://platform.kimi.ai/docs/pricing/chat#model-pricing
pupppet 13 hours ago
selectodude 14 hours ago
Opus 5.5 is about the same price as Kimi K3.1 Pro Highspeed.
polski-g 11 hours ago
OpenAI allows you to use serviceTier=flex, dropping their price by 50%.
And not to mention the gargantuan amount of tokens you get with the US labs' subscription plans. I still cannot see a reason to use this as an end consumer.
simondotau 8 hours ago
Kimi K3 has been my go-to model for its writing style and (prior to Muse Wonder) my go-to for a third opinion during multi-round/multi-agent analysis tasks. Its writing style is IMHO so good that, for code which humans need to review, I regularly got it to clean up the painfully verbose comments left by Opus.
I'm excited to see if its writing style and unique takes have been retained in this new release.
nicolamanzini 8 hours ago
Kimi K3.1 Pro High is on threejseval if you want the 3D version.
Same Three.js prompts as the rest of the field, blind human votes, ranked by quality and cost. Full set of 16 scenes is live at about $0.19 a scene (about $2.97 for the set).
keyle 6 hours ago
It's on openrouter
https://openrouter.ai/moonshotai/kimi-k3.1-pro
I'll wait for the openweight... btw double the price for 67 TPS... Hardly 'nitro'.
brianritz 15 hours ago
Maybe this was why the “AI trade” was weak this week.
WASDx 14 hours ago
Their benchmark result table is broken in Firefox.
yorwba 14 hours ago
document.querySelector("table").style["table-layout"] = "auto";chalmovsky 12 hours ago
software is solved what r u talkin bout?
KronisLV 12 hours ago
Wonder whether they're close to Opus because they're routing to it again or what: https://news.ycombinator.com/item?id=49647300
To be fair, there were some arguments to the opposite, but an odd situation to be in anyways: https://news.ycombinator.com/item?id=49654350
npn 12 hours ago
It is pretty obvious anthropic is lying yet again if you think about it rationally.
Unlike Claude models which always hide the thinking process, Chinese models always show it. So how the heck they can delegate the api call to anthropic and still get the full reasoning? Yes there are tricks to reveal the thinking output, but they are just tricks and do not works reliably. So what would happen when they failed to do it? Cancel the ongoing token generation and revert back to it own model? What about the glitches, the delays, the changes in behavior?
I would understand if the attempts are small in volume, because normally people hardly notice it, but anthropic claims that they happened for millions of calls. Such large numbers would surely get noticed by Chinese users and got reported in the tech forums like linux.do. yet we haven't seen any sight.
smurf9852 11 hours ago
They probably took real inputs and served their owned model to the user, while also getting the response from Claude to compare/train
npn 11 hours ago
staticman2 11 hours ago
I agree we shouldn't believe Anthropic but if you wanted to scam people into thinking they weren't using Claude wouldn't you simply generate synthetic COT?
npn 11 hours ago
TuxSH 15 hours ago
> For the open-weight release of K3.1 Pro, we identified and removed cyber-related data from both training stages, while retaining the general-purpose coding tasks needed for model usefulness. We will continue to apply appropriate controls at every training stage, of which cyber-related data identification and restriction is one example.
Lame.
AspireOne 14 hours ago
I like it. If the increase in unrestricted cyber capabilities can be slowed down, please be it. The world needs to get ready, and that takes time. Way more time than even a slow progress would allow.
Unless you want to see more of what happened the past few days.
I think the argument that "cyber capabilities should be democratized, thus keep producing them now, fast, and for everybody" is a very naive one.
2001zhaozhao 11 hours ago
I am glad that at least one Chinese company seems to be listening to AI cybersecurity concerns and did concrete steps that actually reduce the problem. This was probably at least somewhat costly to them in terms of general model capabilities as well. They'd probably have gotten slightly better coding capabilities if not for removing the cyber training data and tasks.
AspireOne 10 hours ago
LinXitoW 9 hours ago
How does "the world" get ready, when these limits are so hard core that Opus regularly stops working when I'm just trying to find and fix security exploits in my apps?
Currently available, unhindered models can already find a bunch of exploits, not because they're smart, but because they're cheap and smart enough to just keep going for hours or days until it finds something.
The defenders, especially in the FOSS space, only have one big advantage: Unified scale. If defender A finds a vuln, then defender B doesn't need to find it again. Attackers generally act alone, so they need to do all the work themselves.
If we remove a bunch of defenders, the attackers are back at it again.
TuxSH 10 hours ago
Most low- and medium-handing fruit vulns can be found and exploited by GLM and some knowledge already.
Kneecapping cyber vulns only serve governments, Pandora's Box is already open for cyber-related stuff.
AspireOne 10 hours ago
jrflo 12 hours ago
Yes, thank you Moonshot for not throwing open Pandora's box and seeing what happens security wise.
0xbadcafebee 11 hours ago
> The world needs to get ready
How will it do that without a model that's good at security? You gonna have humans manually secure the millions of lines of new AI-generated code, in addition to the existing code? Suddenly people will start doing the job they haven't been doing up to now? Not only are we not capable of auditing all the code, it would take decades to finish, and new code will be coming out at the same time. We can't catch up by hand.
The only way to fight this fire is with fire. We need AI hacking tools to find our security holes quickly and patch them. Otherwise we're just churning out more insecure software, and the only people who can defend against it are the governments who don't want to patch the holes (because they want to be able to exploit them). Without open tools, we all lose.
AspireOne 10 hours ago
CamperBob2 12 hours ago
If I were them, I'd release the weights and claim I had nerfed them for safety, having done no such thing in reality.
rudolftheone 15 hours ago
Hallu Bench Hard: K3 at 23.4%, K3.1 at 8.3% which is very nice improvement!
guybedo 13 hours ago
it gets harder by the day to justify >$1T valuations for OpenAi and Anthropic
jrflo 12 hours ago
Even with Chinese models this close Moonshot only makes $1B in revenue compared to $60B for Anthropic. Enterprises (where all the real money is) will almost always pick a turnkey solution like Anthropic rather than messing around with running their own open weight setup
Slartie 11 hours ago
Nobody has to "run their own setup". Just buy inference from one of the many different open weight inference providers out there. You can use non-chinese ones as well if you don't trust Moonshot AI.
At this point, the only reason why Anthropic has an advantage is laziness on the deciders' side (of which there is a lot) and, for non-coding work, the Claude harness is significantly better than most alternatives. For coding there are several model-agnostic alternatives on par or better than the frontier labs' own offerings. But arguably that is not yet true for office/document work.
staticman2 10 hours ago
If you only have to look at revenue to determine the value of a company stock picking must be very easy for you.
Calculate the price to revenue ratio of all companies and select whichever ones have the best ratio.
jrflo 10 hours ago
guybedo 11 hours ago
i agree with this, "Enterprises will almost always pick a turnkey solution".
For now it's Anthropic. But i don't see how they can maintain this leader position when other companies can provide similar services with models good enough for 90% use cases and at way lower cost.
Anthropic so far is doing a good job building and serving frontier models, they built a nice toolset around it (the web ui, desktop and cli apps ...) but the problem is to justify their IPO price and the huge investments when their moat is so thin
jrflo 11 hours ago
objektif 11 hours ago
I don't think so especially when cost of building software is approaching zero.
yipinwong 14 hours ago
I read somewhere that Chinese SOTA work better in chinese, and worse for English or other languages.
I rarely use any other languages but English for LLM tasks for reasons of sharing across the world.
Maybe that explains Chinese models been subpar for me. Don't tell me the bench marks here are based on Chinese languages only.
Unless I see the diff, I won't use more Chinese models be it cheaper or faster since I can't get the same perf/intelligence with English.
kristopolous 12 hours ago
I've consistently heard the opposite from Chinese programmers. Maybe the performance is better in some tasks or maybe the sample size of San Francisco is just skewed.
a3nz3g 6 hours ago
I feel like many models are overfitting. When it comes to software development, only Opus actually saves me time.
Sol requires some back-and-forth. Other models, like Muse Wonder and Argon, are a total waste of time. They require way too much effort to get things working.
Given the same prompt, Opus can work for hours to deliver a solid result, though it sometimes overengineers things. Sol takes about 80% as much time and delivers a slightly worse version.
Other models just tell me they're done after 20 minutes.
WTH? Am I using the model, or is the model using me?
bel8 an hour ago
Are you using same harness/agent on all of them? It makes a huge difference for long running tasks.
lucagiftzek 8 hours ago
The china models are extremely interesting, first the new releases from deep seek, now this. The modern race to AI is better than it were the race to the moon.
rglover 13 hours ago
Using it now via API (3.1 Pro on Open Router) in a HITL setup (Cline in VSCode).
Off-hand it's quite good. I've been using K3 for the past few months almost exclusively for coding work and have been stunned by how good it is. Excited to see how far 3.1 Pro can be pushed.
sann2011 4 hours ago
what's the general tool recommendation for testing all these releases? I mean like a good frontend. I know of open router for accessing these.
vikramkr 12 hours ago
Is highspeed a different model like a flash model or is that just a api/platform feature thats a normal fast mode? I can't tell from the announcement but I might just be missing something obvious?
0xbadcafebee 12 hours ago
Same model, faster inference
volf_ 15 hours ago
That's quite an impressive jump
secondary_op 3 hours ago
the west perceived hegemony is cooked, so long, and thanks for all the hollywood.
cesarvarela 14 hours ago
I wish Opus 5.5 had an alternative just for the sake of not having a monopoly, but I have yet to see a model live up to its benchmark scores except for Fable and Opus; there is something about Anthropic that no other lab has.
vessenes 14 hours ago
Astra is very strong.
cesarvarela 8 hours ago
Yeah, but it's not good enough. Ask Opus and Astra to make a landing page about lemon pies or whatever. Opus will get you a better result almost every time.
Quitschquat 12 hours ago
What are you using for testing vulnerabilities in your own code?
Claude gates on me like a stupid nanny with some cybersecurity bullshit (like bad actors haven't found a way around).
simonw 14 hours ago
Pelicans are solid: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Here's Kimi K3 for comparison, though I didn't try that on different reasoning levels: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
Update: I ran all three reasoning levels against K3 again: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...
jorgen123 13 hours ago
I think I have yet to see a pelican where the left leg and pedal are drawn on the left side of the bike.
simonw 13 hours ago
There have been a few that get that right - most notable Qwen 3.8 27B running on my laptop: https://simonwillison.net/2026/Aug/16/qwen-38-27b/#the-defau...
Also the recent Geminis - https://simonwillison.net/2026/Oct/13/llm-gemini/ - and GPT-6 Astra on Max: https://static.simonwillison.net/static/2026/gpt-pelicans-gr... - and Claude Fable 5.1 https://static.simonwillison.net/static/2026/claude-pelicans...
CamperBob2 13 hours ago
GLM 5.3 not only got that part right, but animated it: https://crimson-jeri-74.tiiny.site/
To be fair I have a feeling that if you added 'animated' to the SVG request, the output quality from many other models would improve, just because of the extra chain-of-thought work needed to fulfill the more complex request. IMHO the animation requirement should be added to the canonical pelican prompt.
minimaxir 13 hours ago
Simon's comment apparently got flagkilled; I vouched for it.
If enough people are flagging it, we may be at a point where the pelican benchmark is truly overdone.
gnabgib 10 hours ago
Please do not decrease the useful signal with this noise
mi_lk 11 hours ago
Is that even a debate at this point? Doing my job as a netizen to maintain signal/noise ratio
tetraodonpuffer 14 hours ago
definitely not frontier though, as even on max both legs are in front of the frame; although I am wondering how much getting that right correlates with model intelligence.
simonw 14 hours ago
The biggest (of many) failing of the pelican test is that it's only one prompt - what matters most these days is how well a model can drive a lengthy agentic tool calling session.
MrBuddyCasino 13 hours ago
I like the low effort one most.
ciefa 14 hours ago
Can I just say that I love how you are also just always here the moment something drops lmao. Hope you're all well! The pelicans indeed are solid.
Aboutplants 15 hours ago
If those are true then wow
cosmojg 14 hours ago
The announcement page is very extra: https://www.kimi.ai/blog/kimi-k3-1-pro
mixtureoftakes 14 hours ago
looks extremely impressive, the full benchmark table isn't opening for some reason though so do we really have agi if small important things like that keep breaking?
WASDx 14 hours ago
It's broken for me in Firefox, worked with Chrome.
ricky_risky 7 hours ago
kimi seems routing the input into different models, hard problems tend to take much longer time and chain-of-thought than easy problems even if the selected model is k3.1 pro
codeulike 14 hours ago
How does it do on DishwasherBench?
henry700 14 hours ago
Great idea for handling their cyber, by nerfing the model specifically for cyber through removing cyber data from pretraning. This is a way better approach than refusal, which can be trivially abliterated out.
If someone wants to use this model for hacking they will have to train the 3T weights to do so, at that point it's better to use GLM 5.3, so by making it economically unviable to use their models for offensive cyber Kimi has effectively made themselves immune to being targeted in the cyber regulation push efforts.
This is what *actually* pacing the (cyber) frontier looks like.
zozbot234 14 hours ago
Post-training (i.e. RL fine-tuning) not pre-training. This is just a post-trained checkpoint of the K3 pretrained model.
henry700 13 hours ago
Oops. Yes. Thanks!
pcwelder 14 hours ago
Biggest gripe with K3 was slow responses, partly due to inefficient thinking. So far K3.1 pro is almost twice as fast as k3 on our benchmark.
rvz 14 hours ago
This is a frontier level model and is at worst 1 month behind Anthropic and OpenAI.
Imustaskforhelp 14 hours ago
Which is also gonna be open weights on 4 Nov.
When the frontier is pacing itself in its speed in terms of adding new capabilities (notice how fast opus 5.5 got released after Astra), then that also means that the open weights models which were just behind are accelerating in their speed just as much as well.
Good news for us because the models which used to feel 6 months behind now feel like they are lesser.
Double threat to Anthropic and OAI because if open weights models become good enough at the current level of Sota while being cheaper (which time will tell if this model fits the bill or not), then people will use those models instead of OAI/Anthropic provided it is "good enough"
Though it has to be said that only real world use case can be trusted but I remain optimistic and hope that this turns out to be good in real world use cases as well.
But in my opinion, all of this is really good for us end users!
inknight 13 hours ago
> then people will use those models instead of OAI/Anthropic provided it is "good enough"
The only reason people aren't doing this is that hardware prices are high, thanks to, well, OpenAI and Anthropic :D
I wonder when will this madness end
Haunt1000 13 hours ago
SWE2 is post trained apparently on Kimi 3. Using it now on Devin, as it's free until the end of the month for a pro account (hey, $20 a month), and it's pretty strong. If I had to pay for tokens I'm not sure how efficient it would be, but definitely Kimi 3 seems a great base. I co-code with ChatGPT 6 and between the three of us it's pretty effective.
So interested to see what the Kimi 3.1 has to offer.
dom96 14 hours ago
So I just created a brand new Kimi API account and it seems I have no access to this new model. Is this expected?
jiraiyasarutobi 13 hours ago
Wow. that's a beautiful website
minimaxir 14 hours ago
Not the point, but did Moonshot AI announce this at Saturday 1 AM in China? Weird timing for a model drop.
dannyw 6 hours ago
Maybe limited compute to handle launch traffic spikes?
Still get the model out there.
drcode 14 hours ago
makes you wonder if they have intel on an upcoming model drop by the frontiers
eunos 13 hours ago
GLM maybe
hartator 14 hours ago
Benchmarks seem amazing. Rivalzing with Opus 5.5 is something.
I wonder when the Artificial Analysis bench will be out?
maxdo 13 hours ago
this is fun to watch, next week : new fable and astra, also where use muse wonder in this benches? they where leading model in many of these charts.
chrsw 14 hours ago
So, the US economy spends trillions of dollars to be at the "frontier" and China puts out a model that basically does the same thing, for free, and for a tiny fraction of the development cost. How is this sustainable?
SXX 14 hours ago
It's not like US companies spend trillions on training itself.
Mostly it's datacenter build out and circular financing magic when the same dollars being commited multiple times by multiple companies passing hot potato to each other. They basically commit capacities 2-3 years ahead.
hgoel 14 hours ago
It's 'sustainable' because there's enough regulatory risk to using Chinese models that many will avoid them, and a 3T parameter model is still a bit beyond even many enthusiasts for running locally.
ashkankiani 13 hours ago
That regulatory risk argument won't work forever. It's the same with how the US bans chinese EVs which is why Tesla has high market share in the US, but in the rest of the world, chinese EVs are doing big numbers. The future is going to be full of surprises.
verdverm 13 hours ago
There are US companies hosting the open weight models in US data centers.
hgoel 11 hours ago
MangoCoffee 14 hours ago
its hyperscalers and neoclouds data center build out that ate those trillions.
a lot of those money is the commitment from US AI labs that's not yet spend until the data center is roll out.
you are conflating.
chrsw 13 hours ago
Maybe I'm conflating. I could be dead wrong about all this. But I'm trying to zoom out and look at the big picture. So, I'm letting the details sort of blend away and I'm just asking myself: "Is such a large financial sink in our economy, at the macro level, really going to offer the value that the investment warrants?". So, the particulars of who exactly is spending what where I guess doesn't concern me as much. What I'm thinking about is American companies, American people, American dollars going to something that seems like an iffy value proposition.
Now, if you tell me American businesses are turning cheap Chinese tokens into goods and services of high value, for Americans and people all over the world, then obviously I would have a different outlook on what's happening here.
jrflo 11 hours ago
phoghed 14 hours ago
There would be no Chinese model without US models to distill though. So, in a way, the Chinese models also cost a trillion dollars, they just don’t cost China that much.
SomeonesAccount 15 hours ago
No AA scores yet.
minimaxir 14 hours ago
Page isn't up but it's a 55 (4th overall) https://x.com/ArtificialAnlys/status/2113688083145314416
kocial 14 hours ago
No comparison against Gemini 4 Argon?
alexdykyi 7 hours ago
kimik2.5 flash was the game changer
sergiotapia 14 hours ago
What is the best subscription to use with Kimi to use for software engineering work? And how is usage? I remember when K3 came out it burned through usage at an insane rate. Is this still the case with Kimi K3.1 Pro?
esafak 13 hours ago
It seems so, judging by quotas on https://opencode.ai/go
justauserid 40 minutes ago
Do you use OpenCode Go? Any way to speed-up the response times? It's painfully slow right now. Or that's the cost? :)
sergiotapia 12 hours ago
https://x.com/LLMJunky/status/2113692382268936566
Their plans are utterly worthless seems like. Will avoid.
scotty79 14 hours ago
> Kimi K3.1 Pro is a post-trained version of Kimi K3, with substantially larger post-training compute.
It's very nice that we entered a time where models are large enough and we can push the frontier just by training them longer.
When the next generation of gardware comes the ones on the smaller size will be running on a computer that might cost as little as a good car.
So after a home and a car, next major family purchase might be personal AI. And when the robots get good, pehraps in a decade, a fourth major purchase might pop up that will pair nicely with the third one.
Why would a family need an AI? Maybe it's the same kind of question as why would it need a personal computer.
cardboard9926 14 hours ago
55 on AAI, really awesome
I_am_tiberius 14 hours ago
That's incredible
the_real_cher 9 hours ago
Is Kimi abliterated or uncensored?
lucrbvi 9 hours ago
no
rafaelero 15 hours ago
That's nuts.
cogman10 14 hours ago
I've not tried it out, but in the past I've been pretty disappointed in the performance of Kimi models. Deepseek, Qwen, and GLM all appear to perform much better even though Kimi often has higher benchmark scores. Ditto for Mimo.
RussianCow 14 hours ago
The older Kimi K models (2.5 and 2.6) weren't bad for the time, but all of their models have had problems with overthinking. This also makes them significantly more expensive in practice than their pricing suggests, since they produce way more output (reasoning) tokens than most other models. Anecdotally, I've also had problems with all the pre-K3 models thinking themselves in circles trying to solve very simple problems that other models didn't struggle with. (I haven't played with K3 much because it's just too expensive.)
akazantsev 13 hours ago
Same for me, however! Check the price-per-task table. They claim to be cheaper than GLM 5.3.
Edit: or they lie... https://artificialanalysis.ai/models/kimi-k3-1-pro
d0mine 13 hours ago
For me, it is the opposite. It may be slower but it follows the rules better and makes less stupid mistakes, it takes less time to merge the solution.
InsideOutSanta 14 hours ago
I have the opposite impression. I find K3 to be extremely capable at full-stack work; its UI design skills are great. I'd love to use it more, but the quota on Kimi's plans is abysmal. I wonder if these new models improve that.
taytus 12 hours ago
I loved kimi, but had the same issues with usage limits. Now is too late for me to comeback.
cmrdporcupine 14 hours ago
Yep, and often actually very expensive to use. More expensive than the frontier models because there's no realistic coding plan.
AmazingTurtle 14 hours ago
whats the decode tok/s speed?
springtimesun 13 hours ago
<thinking>
threepts 14 hours ago
if this model is truly not distilled/benchmaxxed, then why are not investors pouring trillions into moonshot?
staticman2 11 hours ago
Your question is vague and you didn't explain your point of confusion but consider the fact that securities laws are not fungible between nations.
program_whiz 12 hours ago
first time? Welcome to the irrational SV investor world. Its about hype, perception, politics, perceived future returns, not actual market fit and the proven viability of a technology. Its pets.com, myspace, and NVIDIA pumps because people want to 10x the money now.
Everyone and their dog has been saying its a bubble, there is no moat, this is all known techniques being scaled (very inefficiently) onto increasingly expensive hardware clusters at exponential cost, etc.
MrBuddyCasino 13 hours ago
Now I wanna see its slopcode ranking.
dcchambers 14 hours ago
Wow.
tonyhart7 13 hours ago
its better than trillion dollar companies model (Argon)
shaohua 15 hours ago
"We Must Pace the Frontier"?
redox99 15 hours ago
This probably doesn't move the frontier, it just sits at the current frontier (opus 5.5).
Chinese models never agreed to the pacing anyway lol.
Alwayshasbeeb 15 hours ago
Maybe not the raw intelligence/bench frontier but probably the cost per intelligence frontier.
redox99 14 hours ago
enjoyyourlife 15 hours ago
"We must start a cartel with Google, Meta, and OpenAI"
LZ_Khan 12 hours ago
these motherfuckers went from distilling claude to distilling ChatGPT lmao
bel8 28 minutes ago
it's better than all OpenAI models
Jowsey 15 hours ago
Tech blog and benchmark scores now available here: https://www.kimi.ai/blog/kimi-k3-1-pro
It appears to be generally frontier-level.
dom96 12 hours ago
Ran it on my adversarial programming language (KillSwitch) benchmark[1]. Very significant improvement over K3. On par with Gemini 4 Argon and Fable 5.1. Much slower than both though.
But this is now the highest scoring open-weight model. Amazing stuff.
thefourthchime 11 hours ago
Why does your benchmark have Opus 5 scoring the highest?
wolttam 10 hours ago
Because Opus 5 is the best at their benchmark.
dom96 10 hours ago
red-breeze 7 hours ago
its not open weight.
cromka 13 hours ago
Can someone please tell me what benchmarks to look for that measure world knowledge? For sspitballing, critical analysis, business projects, etc. Is the model size the only way to measure it?
yshamoun 13 hours ago
AA-Omniscience
jampekka 12 hours ago
AA-Omniscience is done with search off though which is not necessarily a very common scenario nowadays.
Super3000 14 hours ago
I'll wait for the pelican benchmark.
fenderog 8 hours ago
here's a fun benchmark https://fenderog.com/art-crit/page.html?p=ceate-an-svg-of-an...
doctoboggan 14 hours ago
I always assume they are benchmaxxed until proven otherwise.